AI Inference Economics Will Be Defined by Dynamic Pipelines
The next infrastructure advantage will come from optimizing complete AI pipelines, not isolated model calls.
For the first generation of enterprise AI, infrastructure economics were reduced to a familiar question: How cheaply can we run this model?
That question is becoming obsolete.
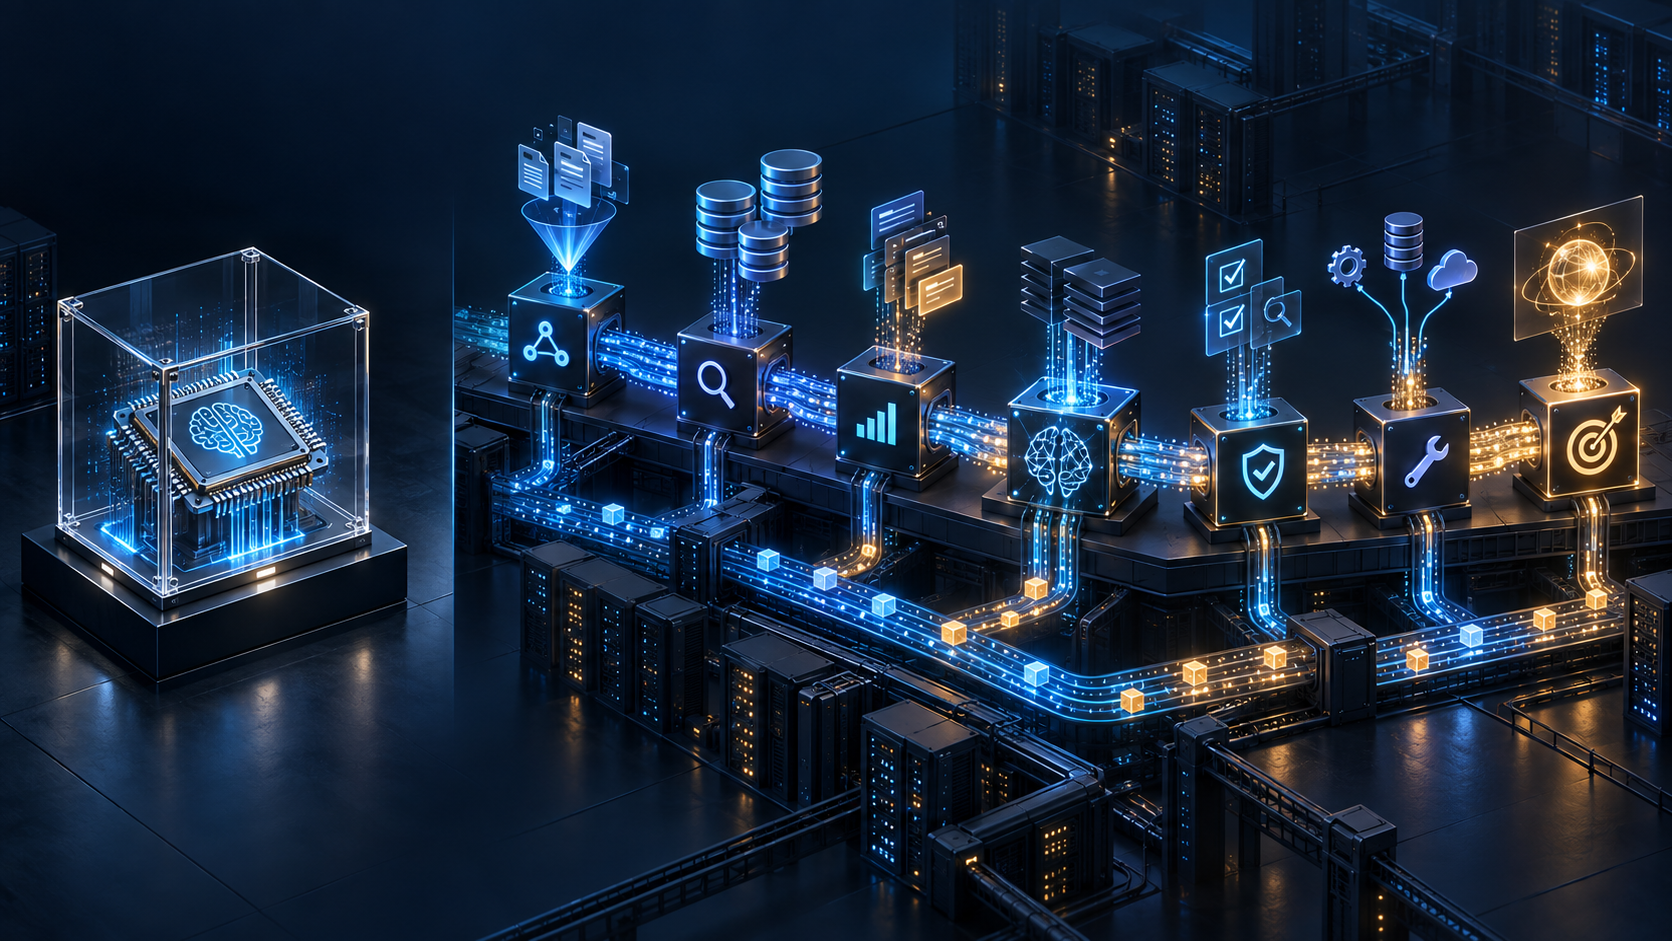
A production AI request is rarely a single model invocation. It is a pipeline: classify the task, retrieve context, rank evidence, assemble a prompt, select a model, generate a response, call a tool, validate the output, and sometimes escalate to a human. Each stage has different compute characteristics, latency sensitivity, accuracy requirements, cache behavior, and failure modes.
The economically meaningful unit is no longer the model. It is the successful pipeline outcome.
This changes the optimization target. The winning AI platforms will not simply serve tokens at the lowest nominal price. They will continuously route and schedule work across models, accelerators, caches, retrieval systems, and service tiers while preserving an application’s quality, safety, and latency objectives.
Inference economics will be defined by the control plane that manages this dynamic pipeline.
1. The Old Unit of Optimization vs. the Pipeline
Traditional inference planning starts with model-level variables:
- accelerator type;
- model size and precision;
- batch size;
- tokens per second;
- GPU utilization;
- and cost per million tokens.
These metrics matter, but they describe a component rather than the business transaction.
Consider a customer-support assistant. A single user request may trigger:
Request admission
  → intent classification
  → policy retrieval
  → account lookup
  → evidence reranking
  → response generation
  → groundedness check
  → tool authorization
  → external action
  → outcome verification
Reducing the price of the generation step by 20 percent may have little impact if retrieval is repeated unnecessarily, a poorly chosen model causes retries, the validator rejects too many responses, or the workflow escalates cases that a better route would have resolved.
◎The correct denominator is not tokens. It is the cost of a verified business outcome.
Examples include:
- cost per case resolved;
- cost per approved claim;
- cost per completed software change;
- cost per qualified lead;
- or cost per answer that passes a defined quality and safety threshold.
This is not only an application-layer idea. Modern serving systems already expose pipeline behavior below the application. NVIDIA Triton’s ensemble abstraction models preprocessing, inference, and postprocessing as connected stages, while its dynamic batcher adjusts batching within latency budgets. That is an early infrastructure expression of the same principle: inference is a dataflow, not an isolated call. NVIDIA Triton ensemble models NVIDIA Triton dynamic batching
Large-language-model serving makes the pipeline nature even more obvious. Prefill and decode have different resource profiles. Prefill processes an input sequence in parallel and is compute intensive; decode generates tokens autoregressively and is often constrained by memory movement and batching behavior. Research systems such as DistServe separate these phases so resources can be assigned according to time-to-first-token and time-per-output-token objectives rather than treating inference as one indivisible operation. DistServe
The economic implication is decisive: a model endpoint is not the atomic unit of production AI. A pipeline stage is. And the optimization surface spans the entire path.
2. Economic Routing
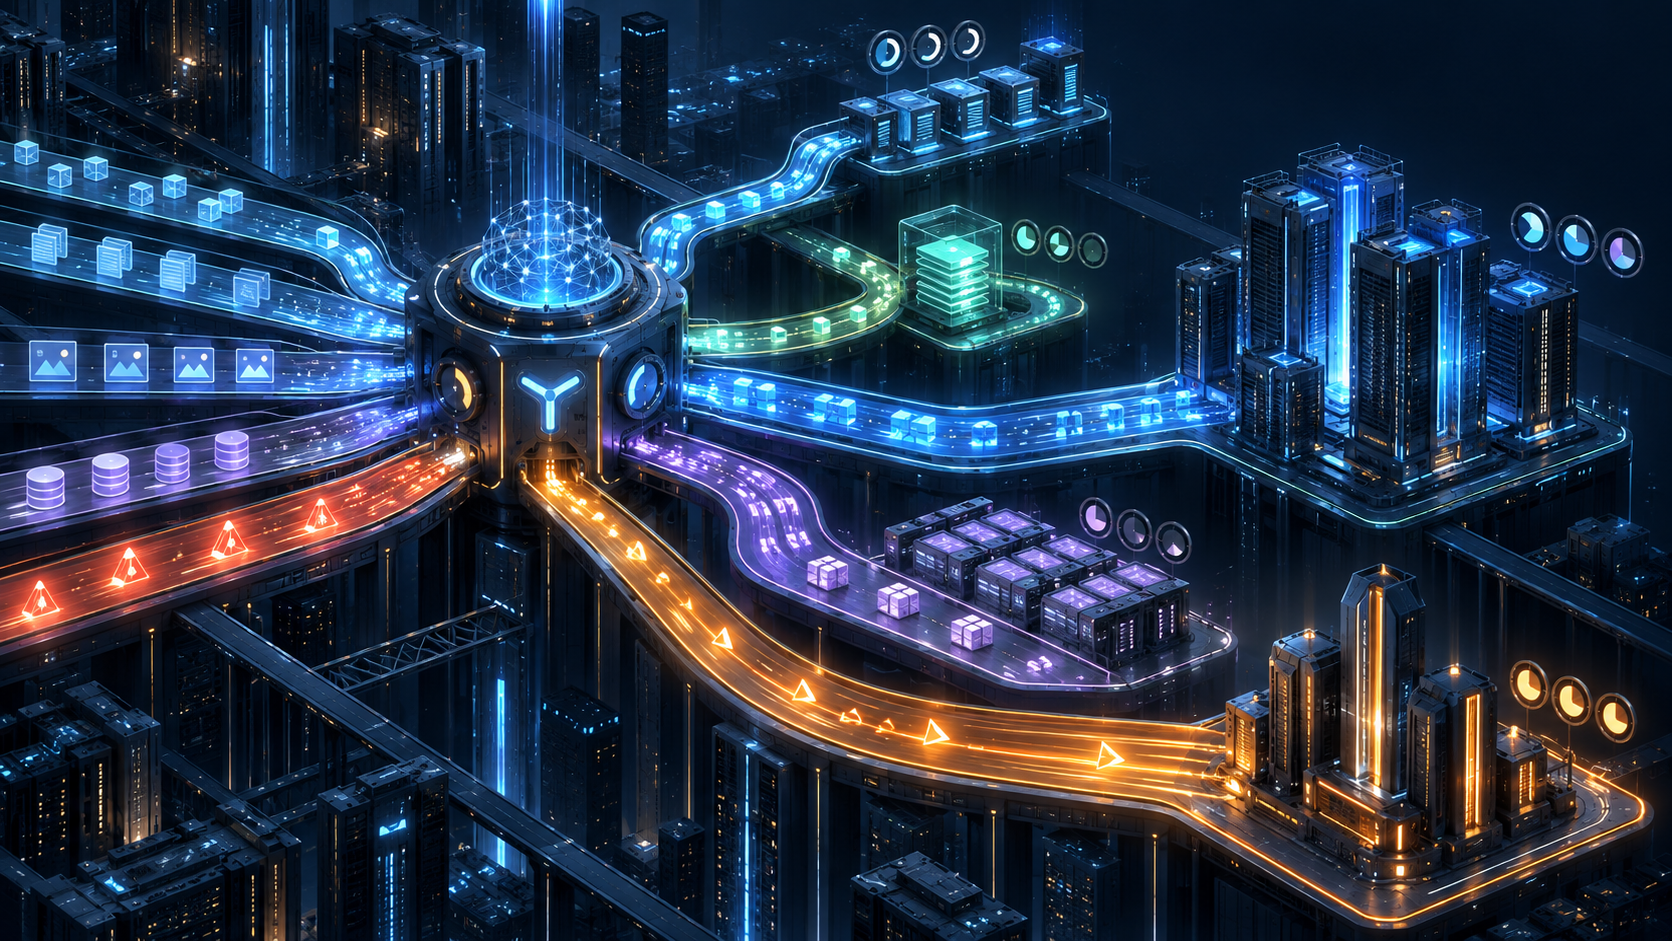
Once the pipeline becomes the unit of optimization, routing becomes an economic function.
A production router should not ask only, “Which model can answer this prompt?” It should ask:
Which combination of model, serving path, context strategy, validation depth, and service tier has the lowest expected cost while meeting this request’s quality and risk requirements?
That route may be different for every request.
A short classification task may go to a small model on a CPU or modest accelerator. A high-value contract analysis may require a larger model, richer retrieval, and a second-pass verifier. Repeated system context may benefit from prompt caching. Nonurgent summarization may be sent to asynchronous batch capacity. A latency-critical interaction may justify premium processing even when its unit price is higher.
The route should consider at least five forms of cost:
1. Direct inference cost — input, cached input, output, and reasoning consumption.
2. Infrastructure cost — accelerator time, memory residency, network transfer, and idle capacity.
3. Pipeline amplification — retries, fallback calls, validation passes, and duplicated retrieval.
4. Failure cost — incorrect outcomes, human rework, policy violations, and customer abandonment.
5. Opportunity cost — value lost when latency causes a task or user journey to fail.
Research on learned routers shows the potential of selecting between stronger and weaker models based on predicted task difficulty. RouteLLM reported more than a twofold cost reduction in some evaluations without compromising response quality. The important idea is not a specific benchmark result; it is that model selection can be a per-request decision rather than a static application setting. RouteLLM
But model quality and price are still not enough. Queue state, prompt length, expected output length, cache locality, and current accelerator load affect the real cost and latency of a route. Recent latency-aware routing research argues for jointly optimizing accuracy, cost, and expected time to first token because the fastest nominal model may be sitting behind the wrong queue. Beyond Accuracy and Cost: Latency-Aware LLM Query Routing for Dynamic Workloads
Economic routing therefore needs two feedback loops:
- an offline loop that learns which route produces acceptable outcomes for each task class;
- and an online loop that sees current capacity, queue pressure, cache state, and SLO risk.
Without the first, the system may save money by degrading quality. Without the second, it may choose an economically sensible model that cannot meet the moment.
3. SLO-Aware Scheduling
Routing chooses a destination. Scheduling decides when and how the work runs.
That distinction matters because inference efficiency often comes from waiting: holding a request briefly to form a larger batch, reordering work to preserve cache locality, or filling otherwise idle accelerator capacity. But waiting consumes the request’s latency budget.
A scheduler must therefore optimize goodput—the amount of useful work completed within service-level objectives—not raw throughput.
For interactive generation, useful SLOs include:
- time to first token;
- time between output tokens;
- end-to-end completion time;
- and the probability of meeting those targets at the tail, not only on average.
For asynchronous work, the relevant objective may be completion by a deadline at the lowest available cost.
NVIDIA Triton exposes this trade-off directly: its dynamic batcher can delay requests for a configurable period to form more efficient batches, with queue priorities and timeout policies determining when efficiency must yield to urgency. NVIDIA Triton dynamic batching
LLM workloads make scheduling harder because request shapes vary dramatically. A long prefill can stall active decodes. A short response can share a batch with a request carrying a large KV-cache footprint. Arrival patterns are bursty, and tenants may have different priorities.
Sarathi-Serve addresses part of this problem by splitting prefills into chunks and combining them with decode work, reducing stalls while preserving batching efficiency. Its results illustrate why scheduling policy is itself an economic lever: better scheduling can increase serving capacity without changing the model or accelerator. Sarathi-Serve
A production scheduler should make decisions using the remaining SLO budget, not a single global queue rule. It may:
- admit or reject work based on predicted completion time;
- choose synchronous, fast, standard, or batch service;
- prioritize a decode stream approaching its token-latency limit;
- shrink a batch to protect tail latency;
- defer low-priority enrichment;
- or degrade gracefully to a smaller approved model.
Commercial APIs already expose service choices that make this visible. OpenAI’s Batch API trades immediacy for a lower price, while prompt caching changes the cost and latency of repeated prefixes. These options are most valuable when selected by pipeline policy rather than hard-coded into one application path. OpenAI Batch API FAQ OpenAI prompt caching
The goal is not to keep every GPU busy. It is to maximize successful outcomes inside contractual limits.
4. Pipeline Observability
Dynamic optimization is impossible if the system can see only model-level utilization and aggregate token counts.
Pipeline observability must connect technical execution to economic outcome.
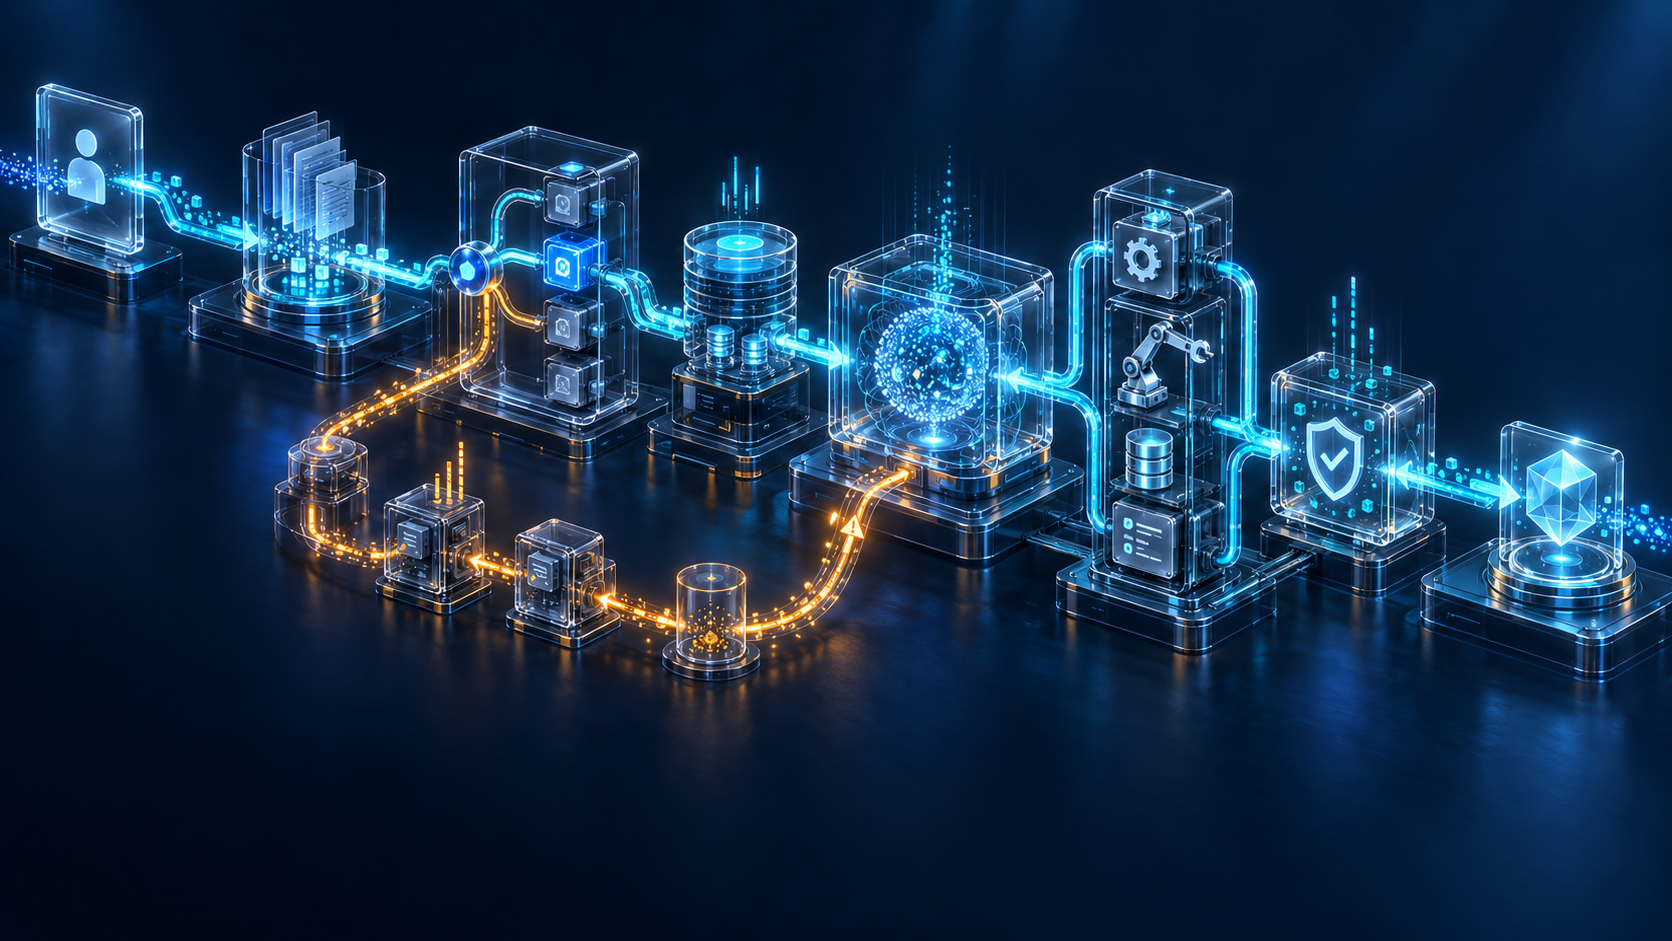
For every request, the trace should capture:
- task and tenant;
- route chosen and alternatives considered;
- model, version, precision, and service tier;
- prompt, cached, reasoning, and output tokens;
- retrieval and reranking work;
- queue time, prefill time, decode time, and tool latency;
- cache hits and misses;
- retries, fallbacks, and validation passes;
- accelerator and memory allocation;
- quality, policy, and groundedness results;
- end-to-end SLO attainment;
- and externally verified business outcome.
The key is correlation. A low-cost model call that triggers two retries may be more expensive than the premium route. A high-throughput batch that misses an interactive latency target creates no useful goodput. A cache hit matters only if the cached context was valid for the same tenant, permissions, and version.
OpenTelemetry’s semantic conventions provide a common vocabulary for traces, metrics, logs, and resources, including generative-AI attributes and measures such as time to first response chunk. Standardization is important because an inference pipeline crosses application services, model gateways, vector stores, schedulers, and external tools. OpenTelemetry semantic conventions OpenTelemetry GenAI attributes
The most useful economic dashboard will not lead with GPU utilization. It will answer questions such as:
- What is our cost per verified successful task by route?
- Which stage is consuming the SLO budget?
- Where do retries amplify cost?
- Which task classes are overprovisioned?
- Which tenants or workloads reduce batching efficiency?
- What is the marginal cost of one more point of quality?
- How much capacity produces useful goodput rather than late work?
Observability turns pipeline economics from an architectural aspiration into a measurable operating discipline.
5. Continuous Rebalancing
The optimal route does not stay optimal. Models, prices, traffic, cache state, and capacity continuously change.
Models change. Prices change. Quantization improves. New accelerators arrive. Traffic composition shifts by hour and season. Cache-hit rates rise and fall. A retrieval index becomes stale. A model that performs well on yesterday’s evaluation set may drift on today’s production requests.
Static deployment choices cannot keep pace with this environment.
The inference platform needs a continuous rebalancing loop:
Observe workload and outcomes
  → estimate demand, quality, cost, and SLO risk
  → simulate candidate allocations and routes
  → shift bounded traffic
  → verify results
  → promote, roll back, or continue exploring
Rebalancing can happen at several timescales.
Per request: select a model, context strategy, cache path, and service tier.
Per minute: adjust queue priorities, batch delay, replica counts, and prefill/decode allocation.
Per deployment: test new models, quantization formats, kernels, and routing policies through replay, shadow traffic, and canaries.
Per planning cycle: revise reserved capacity, regional placement, and the portfolio of accelerators and providers.
The controller must optimize a constrained objective, not chase the lowest observed cost:
minimize expected cost per successful outcome
subject to:
  quality >= target
  safety violations <= threshold
  p95 latency <= SLO
  availability >= commitment
  capacity risk <= tolerance
It must also account for switching costs. Moving a model can require weight loading, cache warming, KV-cache transfer, or temporary duplication. Research on disaggregated serving shows that benefits depend on workload and interconnect conditions; separating prefill and decode is not automatically more efficient in every environment. That is precisely why allocation should be measured and adaptive rather than doctrinal. Revisiting Disaggregated Large Language Model Serving
Continuous rebalancing should remain bounded. Exploration belongs inside a safety envelope with minimum quality floors, tenant isolation, budget limits, rollback triggers, and protected capacity for critical workloads. The system may experiment with five percent of low-risk traffic; it should not discover a cheaper route by violating a customer-facing commitment.
The New Inference Control Plane
The next infrastructure advantage will not come from a single “best” model or accelerator.
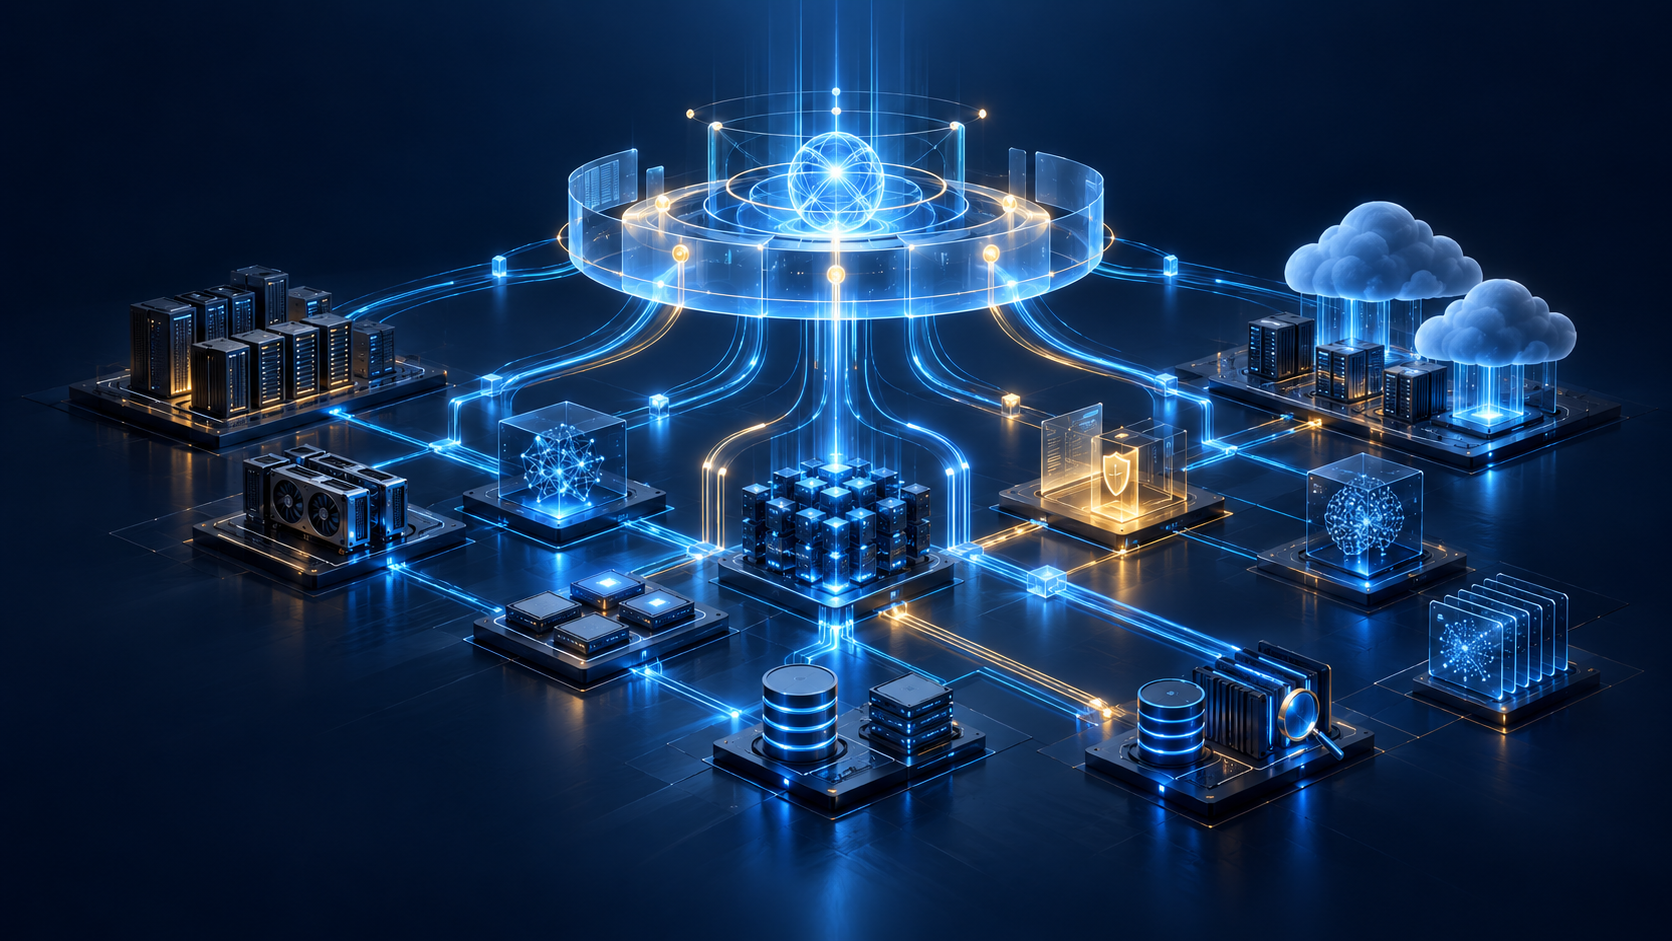
It will come from coordinating a heterogeneous portfolio:
- small and large models;
- CPUs, GPUs, and specialized accelerators;
- local, cloud, and API capacity;
- interactive and asynchronous service tiers;
- cached and uncached context;
- colocated and disaggregated execution;
- deterministic stages and probabilistic stages;
- automated validation and human approval.
This portfolio needs a control plane that understands application intent, economic trade-offs, live infrastructure conditions, and evidence of success.
The old question was:
How efficiently did we serve the model?
The new question is:
How efficiently did the complete pipeline produce a verified outcome within its SLO?
That is the unit that finance cares about, the unit that operators can improve, and the unit that customers ultimately experience.
AI inference economics will be won not by static optimization, but by dynamic pipelines that route economically, schedule against service objectives, expose their full trajectory, and continuously rebalance as conditions change.
Selected sources
- NVIDIA Triton: Ensemble Models
- NVIDIA Triton: Dynamic Batching
- DistServe: Disaggregating Prefill and Decoding
- Sarathi-Serve: Taming the Throughput-Latency Trade-off
- RouteLLM: Learning to Route LLMs with Preference Data
- Beyond Accuracy and Cost: Latency-Aware LLM Query Routing
- OpenAI: Prompt Caching
- OpenAI: Batch API FAQ
- OpenTelemetry: Semantic Conventions
- Revisiting Disaggregated Large Language Model Serving